Category: Performance
-
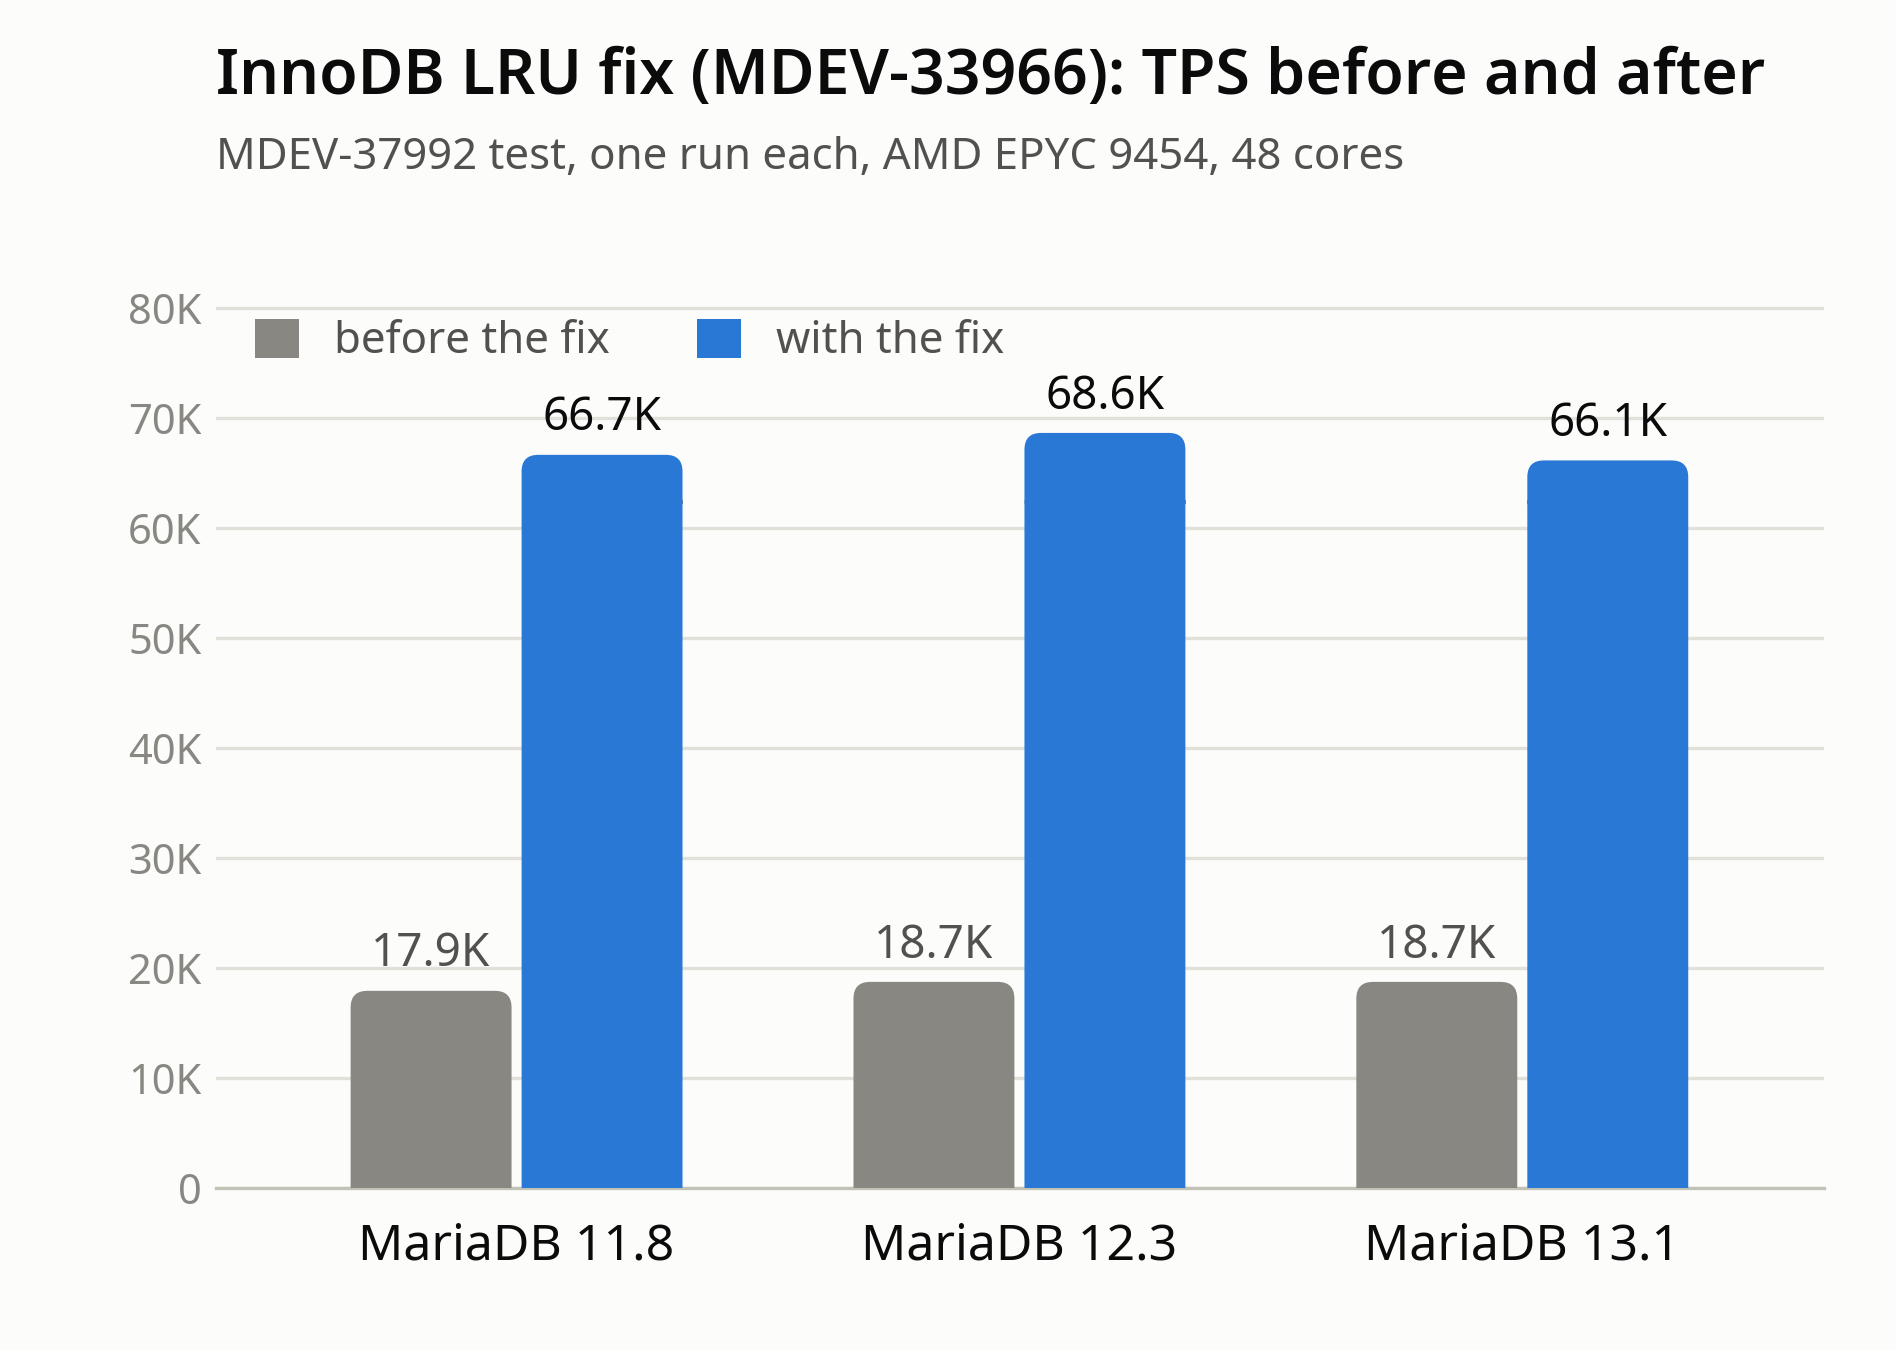
How MariaDB 11.8 became about 3× faster on some in-memory workloads, fixing a regression dating back to 10.5
Publishing on behalf of Alessandro Vetere.
Conclusions first: InnoDB in-memory workloads started paying for LRU management in 10.5, a performance regression, and I think the reason is that a clock, which was meant to say “eviction has started”, began ticking much earlier. A minimal fix would bring back the old meaning of the clock. The fix that we pushed tries to do more: it takes buf_pool.mutex out of the LRU promotion on a page access, not only for in-memory workloads. […]
-
The Man Who Benchmarks MariaDB Against the World
Jonathan Miller has spent 27 years in database performance testing. He talks about TAF, the open source Test Automation Framework that benchmarks MariaDB, MySQL and PostgreSQL side by side, configuration provenance, and how to prove your patch made MariaDB faster.
-
MariaDB Foundation: Exploring TidesDB Performance with TAF
TidesDB now exists inside MariaDB as a pluggable storage engine.
With the TideSQL plugin available, anyone can load TidesDB into a MariaDB server and begin experimenting with it.
But having a plugin is only the first step — you still need a practical, reproducible way to run real workloads against it, that’s where TAF comes in.
This blog exists to give anyone interested in TidesDB a roadmap to the city of benchmarking it — a clear, reproducible starting point for […]
-
MariaDB Foundation: Reproducing and Validating MDEV‑37992 with TAF
Thanks to Mark Callaghan for filing MDEV‑37992. This regression only appears under specific LRU and buffer‑pool conditions, and requires a memory‑resident workload to expose.
Using TAF, I reproduced the issue across 11.8, 12.3, and 13.1 using both parent commits and patched commits from MDEV‑33966. The fix restores expected throughput in all branches.
The workload used was POINTS‑COVERED‑PK with 10M rows × 8 tables, 40 threads, warmup enabled, and a 90G buffer pool. TAF’s warmup iteration, rest detection, and stable‑state perf […]
-
MariaDB Foundation Advances TAF with HammerDB 6.0 and xt_reservoir Integration
Overview
While validating MariaDB RSS stability under stored procedure workloads, I ran into unexpected memory growth. The goal was straightforward: confirm that MariaDB was not leaking memory when running TPROC-C stored procedure workloads. To do this, I used HammerDB TPROC-C SP and added improved RSS monitoring so I could watch memory usage over long-duration runs.
The results were clear. MariaDB RSS stayed stable. HammerDB 5.0 kept growing, and growing.
This led to a deeper investigation into HammerDB itself, and ultimately […]
-
A response to Percona’s 2026 MySQL ecosystem benchmark: useful data, but not a realistic MariaDB comparison
Percona’s new 2026 benchmark report is interesting because it puts several MySQL-family releases on the same graphs and shares a public repository for the test harness. That openness is welcome. But after reading both the article and the published scripts, I do not think the post supports broad conclusions about “ecosystem performance,” and I especially do not think it represents an adequately tuned MariaDB, worthy of a neutral comparison.
Versions
The versions chosen for MariaDB are already a subject of […]
-
MariaDB Innovation: InnoDB-Based Binary Log
I am starting a new series on what makes MariaDB Server distinct from MySQL, highlighting innovations that make the difference.
MariaDB 12.3 introduces a new binary log implementation that stores binlog events directly in InnoDB-managed tablespaces rather than in separate flat files on disk.
This is an incredible innovation; for a long time, binary logs have been a performance bottleneck. DimK pointed it out several times. [1], [2]
The new binlog design halves the number of fsyncs and improves performance, […]
-
Big Vector Search Benchmark: 10 databases comparison

I have benchmarked MariaDB Vector before, but it was a while ago. Users kept asking about Milvus. New pgvector alternatives were gaining popularity. And I simply wanted to see if MariaDB got any better. This benchmark round includes more databases, larger dataset, and no irrelevant datasets that only add noise but don’t really help today in 2026.
Dataset
Now is the AI time. Vector search is used for embeddings generated by LLMs. Most ann-benchmarks datasets are pre-AI and use, for […]